
Next.js content not showing in indexed HTML almost always means the text is added by client-side JavaScript after the first response. Googlebot can queue a page for rendering, but most AI crawlers Vercel and MERJ tested do not run JavaScript. Fix it by rendering the content on the server, then verify with curl.
Key takeaways
- Test the raw HTML response first (curl or view-source), not the browser DOM. If your key sentences are missing there, any crawler that skips JavaScript cannot read them.
- Googlebot renders JavaScript in a second stage, so a page can be indexable yet slow or incomplete. AI crawlers have no such second stage in the data Vercel published.
- In the App Router, content that matters should come from Server Components that fetch data on the server. Remove "use client" and useEffect fetching from anything that carries copy, prices, specs or schema.
- Keep client rendering for non-essential extras such as view counters and chat widgets.
- Check three views per URL: raw HTML, Google's rendered HTML in Search Console, and what AI answers actually say about the page.
Why is my Next.js page content not showing in Google's indexed HTML?
Because the HTML your server sends does not contain the content, and Google has not yet rendered the page, or rendering failed. Google Search Central, November 2026, describes three stages: crawling, rendering and indexing. Googlebot fetches the URL with an HTTP request, then queues pages with a 200 status for rendering unless a robots meta tag or header says otherwise.
That means a client-rendered page is not invisible to Google. It is dependent on a rendering step that can fail or lag. Google's documentation states that server-side or pre-rendering is still a good idea because it makes a site faster for users and crawlers, and not all bots can run JavaScript. Patrick Stox makes the same framing for the framework: Patrick Stox, Next.js SEO notes that Next.js is a React framework, so everything in JavaScript SEO applies.
The seven usual causes in a Next.js app
| Cause | What you see | Fix |
|---|---|---|
| Data fetched in useEffect inside a client component | Raw HTML has an empty shell or a loading spinner | Fetch in an async Server Component, or in getStaticProps / getServerSideProps on the Pages Router |
| Whole page marked "use client" at the top | Copy appears only after hydration | Push the directive down to the small interactive leaf components |
| Content behind a tab, accordion or click handler that loads on demand | Text absent until a user acts | Render all copy in the initial HTML and hide it with CSS or the details element |
| API route blocked by robots.txt or by a bot rule at the CDN | Rendered page is empty only for crawlers | Allow the endpoint, or stop depending on it from the browser |
| JavaScript error during render | Content missing in Google's rendered view only | Collect errors from real sessions and from the URL Inspection live test |
| Client-side noindex or soft 404 handling | Page dropped from the index | Return real status codes from the server; never inject noindex then remove it with JavaScript |
| Metadata resolved late for dynamic pages | Title or description appears in the body rather than the head for some bots | Check htmlLimitedBots and prerender where you can |
On the last row: the Next.js documentation, as checked November 2026, says the metadata object and generateMetadata are supported only in Server Components, that dynamically rendered pages can stream metadata, and that prerendered pages do not stream it because metadata is resolved at build time. Streaming can be customised or disabled with the htmlLimitedBots option.
On the noindex row, Google's documentation warns that when it meets a noindex tag it may skip rendering, so using JavaScript to remove noindex may not work.
Can AI crawlers read JavaScript-rendered content?
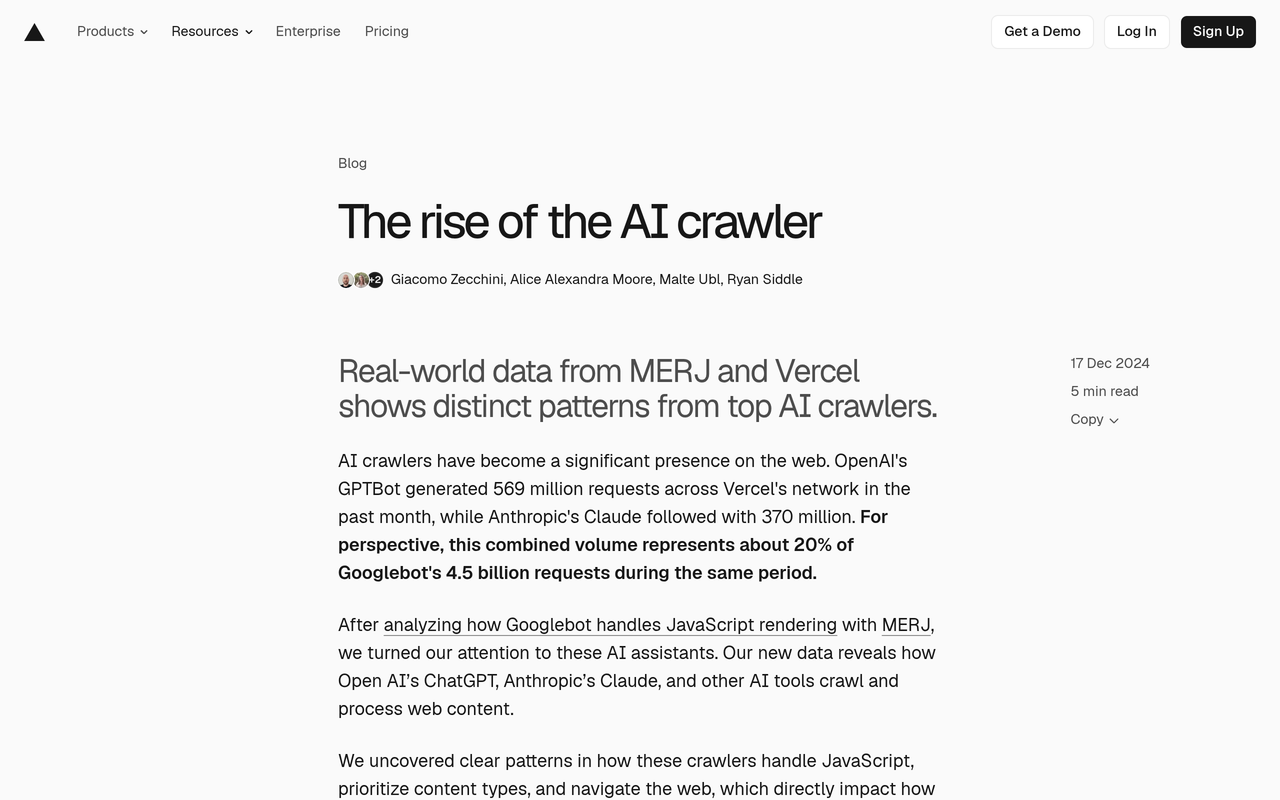
In the only large public measurement we found, no. Vercel, December 2024, analysed crawler traffic with MERJ and reported that OpenAI (OAI-SearchBot, ChatGPT-User, GPTBot), Anthropic (ClaudeBot), Meta (Meta-ExternalAgent), ByteDance (Bytespider) and Perplexity (PerplexityBot) did not render JavaScript. Its own summary of the finding was short: "They can't read client-side rendered content."
The same article gives the scale. In the month measured, Vercel counted 569 million GPTBot fetches and 370 million Claude fetches, against 4.5 billion for Googlebot across Gemini and Search. ChatGPT's crawler spent 11.50% of its fetches on JavaScript files and Claude's 23.84%, yet neither executed them. Downloading a script is not running it.
| Crawler | Runs JavaScript? | Source and date |
|---|---|---|
| Googlebot (Search) | Yes, in a queued rendering stage | Google Search Central, as checked 9 November 2026 |
| Gemini | Yes, uses Googlebot's infrastructure | Vercel and MERJ, December 2024 |
| GPTBot, OAI-SearchBot, ChatGPT-User | No | Vercel and MERJ, December 2024 |
| ClaudeBot | No | Vercel and MERJ, December 2024 |
| PerplexityBot | No | Vercel and MERJ, December 2024 |
| Meta-ExternalAgent, Bytespider | No | Vercel and MERJ, December 2024 |
One limit matters. The data is nearly two years old, and crawler behaviour changes without announcement. Treat the table as a default assumption and re-test your own URLs rather than relying on it. Vendors have not published rendering commitments that we could find, so a server-rendered page is the only version that does not depend on one.
For how ChatGPT's search crawler fits in, see ChatGPT Search: how it works, OAI-SearchBot and citations.
How do I test what each crawler fetches?
Run the three-view test. It takes about ten minutes for five URLs and needs no paid tool.
- Pick five URLs and three quotable passages each. Choose a product or service description, a price or spec line, and the sentence you want an AI to repeat.
- View 1, raw HTML. Run curl -s https://example.com/page | grep -c 'your passage' or open view-source. A count of zero means the passage is not in the response.
- Repeat with a crawler user agent. Add -A 'GPTBot' or -A 'ClaudeBot' to the curl command. This tests whether your server or CDN serves different HTML to bot user agents. It cannot prove a bot is allowed, because firewalls also check IP ranges.
- View 2, Google's rendered HTML. In Search Console, use the URL Inspection tool, run a live test and open the rendered HTML. Google's troubleshooting documentation recommends this tool or the Rich Results Test to check that the rendered HTML has all the content you expect.
- View 3, the answer. Ask ChatGPT, Gemini, Perplexity and Claude a question the page should answer, and note whether your brand or URL appears.
Score each URL by raw-HTML coverage: passages found in view 1 divided by passages tested. An illustrative example: five URLs times three passages is 15 tests. If 6 appear in raw HTML, coverage is 40%, and the other 9 depend on JavaScript. Rank the URLs by lowest coverage and by commercial value, and fix those first. These numbers are an invented worked example to show the arithmetic, not a measurement.
To run a quicker version, use the free AI SEO Checker, which shows whether ChatGPT, Claude, Perplexity and Google AI Mode can read a page, with 30+ checks and the top fixes. Pair it with the free AI crawler checker to confirm robots.txt is not blocking GPTBot, OAI-SearchBot, ClaudeBot or PerplexityBot.
How do I fix it with server rendering in Next.js?
Make the content part of the first response. The route depends on your router.
App Router
- Fetch data in an async Server Component, and pass it as props. Server Components render on the server and send HTML.
- Move "use client" to the smallest component that needs state or browser APIs: a carousel, a filter, a form.
- For pages that rarely change, prerender at build time with generateStaticParams. For personalised or frequently changing pages, render on request.
- Put title, description, canonical and JSON-LD in the metadata export and in the server-rendered markup, not in a client effect. The schema markup for AI search guide covers what to add and how to validate it.
Pages Router
- Use getStaticProps for content known at build time and getServerSideProps where it must be fresh per request.
- Do not rely on a client-side fetch inside useEffect for any text you want read.
If a full migration is not possible this quarter
Pre-rendering is a stop-gap: serve a static snapshot of the page. Google's documentation notes that dynamic rendering is a workaround rather than a recommended long-term solution, so plan the move to server rendering for pages that earn revenue.
What can stay on the client, per Vercel's recommendations: non-essential dynamic elements such as view counters, interface enhancements, live chat and social feeds. Anything an AI should quote goes on the server.
Which fix for which symptom?
| Symptom | Likely stage that fails | First action |
|---|---|---|
| Passage missing in raw HTML, present in Google's rendered HTML | AI crawlers and any non-rendering bot | Move the content to a Server Component |
| Passage missing in both raw and Google rendered HTML | Rendering or script error | Check JavaScript errors, blocked API calls, robots rules |
| Passage in both, page still not indexed | Indexing, not rendering | Check noindex, canonical, duplicate and quality signals |
| Passage in raw HTML, but curl with a bot user agent differs | Server or CDN bot handling | Review bot rules; see ChatGPT agent blocked your site |
How do I confirm the fix reached AI answers?
A clean raw-HTML check proves a crawler can read the page. It does not prove an engine will cite it. Two checks close that gap.
- Crawler logs. Confirm AI user agents are fetching the updated URLs and receiving a 200. The agent analytics explainer covers which bots to watch, and the AI Crawler Policy Kit separates training bots from search and user bots.
- A fixed prompt set. Run the same buyer questions before and after the change, on each engine, over several days. Single answers vary, so judge a change only across repeated runs. The method is in How to track brand mentions in ChatGPT.
Allow time. Re-crawl and re-citation are not instant, and no engine publishes a schedule.
Where Noma fits
Noma by Nurdd is an AEO and AI visibility platform. Its agent analytics reports which AI crawlers fetch each page, and its prompt tracking asks 13 AI engines, including ChatGPT, Gemini, Perplexity and Claude, your buyers' questions every day. It shows whether the brand is named after a rendering fix, and which pages the answers cite.
See it on your own brand: book a demo or start the 3-day free trial. A card is taken at signup so billing can start on day 3; cancel before then and nothing is charged.
Common mistakes to avoid
- Trusting the browser. DevTools Elements shows the rendered DOM. Only view-source or curl shows what a non-rendering crawler gets.
- Testing the homepage only. Templates differ. Test one URL per template: product, article, category, location.
- Hiding schema in a client effect. JSON-LD injected by JavaScript is missed by crawlers that skip scripts.
- Blocking the wrong bot. Blocking training bots is a separate decision from blocking search bots; confusing them removes you from answers.
- Calling it fixed after one answer. Re-test across runs and engines.
How we researched this
We reviewed Google Search Central's JavaScript documentation, the Next.js metadata documentation, Vercel and MERJ's published AI crawler analysis, and an independent Next.js SEO reference. Facts, figures and documentation wording were checked on 2026-11-09. The Vercel data was published in December 2024 and we did not run our own crawler experiment, so the crawler table reflects that study and your own tests should take precedence.
What to do next
Run the three-view test on your five highest-value URLs today, fix the lowest raw-HTML coverage first, then track whether answers change. To measure that across 13 AI engines, book a demo or start the free trial. Plans and prices are on the pricing page.
See what AI engines say about your brand
Free · no account · or start a 3-day trial
Questions people ask
Why is my Next.js page content not showing in Google's indexed HTML?
The content is probably added by client-side JavaScript, so it is not in the HTML your server sends. Googlebot queues pages for a separate rendering stage, which can lag or fail on script errors. Compare view-source with the rendered HTML in Search Console's URL Inspection tool, then move the content into server-rendered components.
Can AI crawlers read JavaScript-rendered content?
In Vercel and MERJ's analysis published in December 2024, GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot and PerplexityBot did not render JavaScript. Gemini used Googlebot's infrastructure and could. Crawler behaviour can change, so test your own URLs rather than relying on one study.
How do I check what a crawler sees on my Next.js page?
Run curl against the URL and search the output for a sentence from the page, or open view-source. Repeat with a bot user agent to catch server or CDN differences. Then run a live test in Search Console's URL Inspection tool to see Google's rendered HTML.
Do Server Components fix Next.js indexing problems?
They fix the rendering cause, because Server Components send HTML that already contains the content. They do not fix noindex tags, canonical errors, blocked crawlers or low-quality pages. Check those separately if the passage is in raw HTML but the page is still not indexed.
Is client-side rendering ever fine for SEO?
Yes, for non-essential elements such as view counters, chat widgets and social feeds, which Vercel lists as suitable for client rendering. Keep anything you want indexed or quoted, such as copy, specs, prices and structured data, in the server response.
Does fixing rendering guarantee I appear in ChatGPT answers?
No. It removes a barrier so crawlers can read the page, but engines choose sources by other signals too. Track a fixed set of buyer prompts across engines before and after the change to see whether your brand is named.